

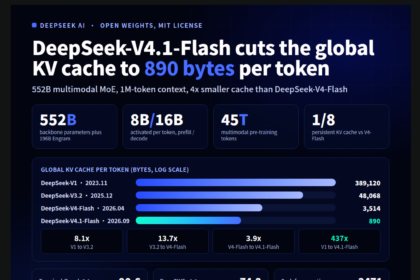
DeepSeek AI Released DeepSeek-V4.1-Flash with 1M Context, FP4 KV Cache, and Cross-Layer Attention Reuse
Unlocking Extreme Context Scaling with DeepSeek-V4.1-Flash As LLM-driven agents increasingly tackle long-horizon…
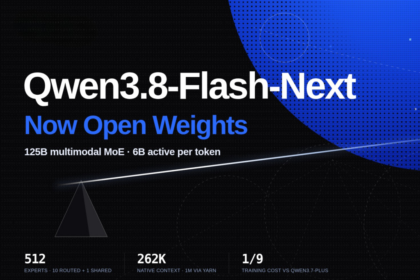
Inside the Architecture of Qwen3.8-Flash-Next: A 125B Multimodal MoE with 6B Active Parameters
A Technical Deep Dive into Qwen3.8-Flash-Next: Efficiency at Scale The landscape of…
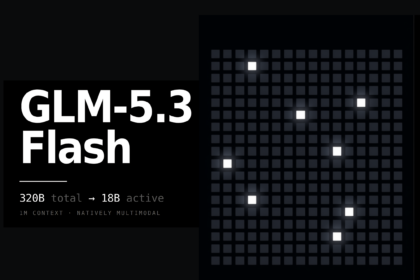
Z.ai Debuts GLM-5.3-Flash: A High-Efficiency Multimodal MoE with 1M-Token Context
A New Benchmark in Multimodal Reasoning Z.ai has officially launched GLM-5.3-Flash, representing…