

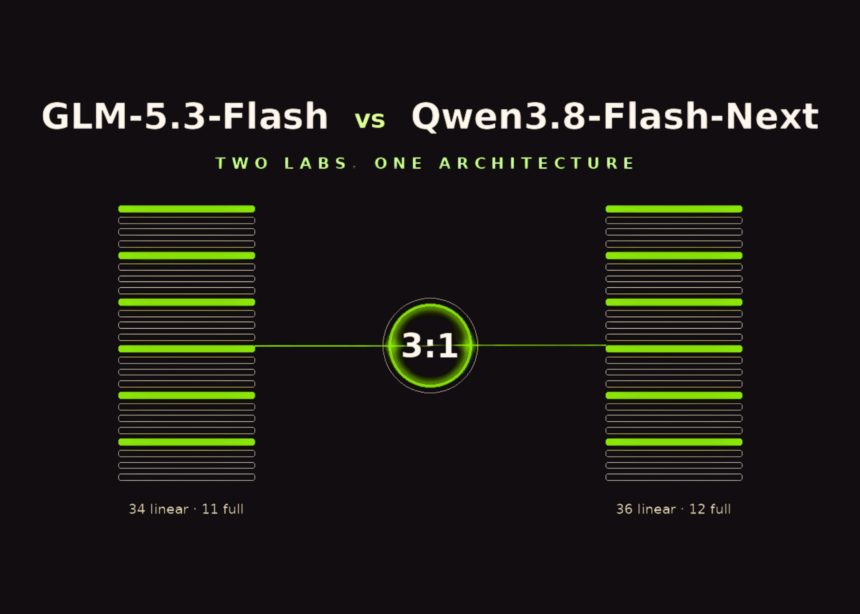
The Great Architectural Convergence
In a fascinating display of independent research paths, two major AI labs in China have unveiled new models that utilize an identical structural blueprint. Z.ai launched GLM-5.3-Flash, and Alibaba’s Qwen team released Qwen3.8-Flash-Next within a 24-hour window. Despite being developed without collaboration, these models share a common architectural philosophy that prioritizes efficiency and long-context capabilities through specific design choices.
The Shared Blueprint
Both models have adopted a hybrid approach to attention, balancing memory efficiency with the need for precise retrieval. They utilize a distinct ratio of 3:1 between linear attention layers and full attention layers. The linear components allow the models to maintain a constant computational cost as input length increases, while the full attention components handle high-fidelity retrieval tasks.
Furthermore, both labs have implemented a specialized indexer for managing context. This system compresses the context window by a factor of 4x before performing a relevance score. The resulting context is capped at a 2048-token budget, allowing the sparse attention layers to operate with high performance despite processing massive raw input windows.
In a departure from traditional transformer design, both models have shifted away from a single residual stream. Instead, they widen the stream into four parallel gated branches. This architectural change allows for more sophisticated gating mechanisms, effectively determining which information is read back from or written to the residual stream at each block.
Data and Architecture Comparison
The following table outlines the key architectural specifications of these two recent releases:
| Metric | GLM-5.3-Flash | Qwen3.8-Flash-Next |
|---|---|---|
| Total Parameters | 320B | 125B |
| Active Parameters | 18B | 6B |
| Linear:Full Ratio | 3:1 | 3:1 |
| Context Compression | 4x | 4x |
| Attention Budget | 2048 Tokens | 2048 Tokens |
| Residual Branches | 4 | 4 |
The Point of Divergence: Positional Encoding
While the architectural foundations are remarkably similar, the labs diverge on the implementation of positional information. GLM-5.3-Flash has opted to remove rotary position embeddings (RoPE) entirely, relying on implicit position information derived from its recurrent linear attention layers. Conversely, the Qwen team tested a NoPE configuration but ultimately retained RoPE. Their research indicated that while NoPE models performed equally well during pre-training, they exhibited significant stability issues during post-training, specifically failing to reliably terminate generation tasks.
The Dissenting Voice: MiniMax
It is important to note that this architecture is not the industry-wide consensus. The lab MiniMax has taken a different approach with its M3 architecture. After extensive internal testing, MiniMax concluded that the inclusion of linear attention layers leads to noticeable degradation in multi-hop reasoning capabilities. As a result, MiniMax has abandoned linear layers in favor of a pure, albeit sparse, softmax attention mechanism, signaling that the debate regarding the most efficient architecture for reasoning is far from settled.



