

The LLM Interoperability Gap
Modern agentic workflows often face a significant architectural friction point: the fragmentation of LLM provider APIs. An agent built on the Anthropic Messages API cannot natively communicate with a backend running an OpenAI-compatible interface, such as NVIDIA NIM, vLLM, or Ollama, without significant refactoring. This creates a technical debt cycle where the agent logic is tightly coupled to the specific provider format.
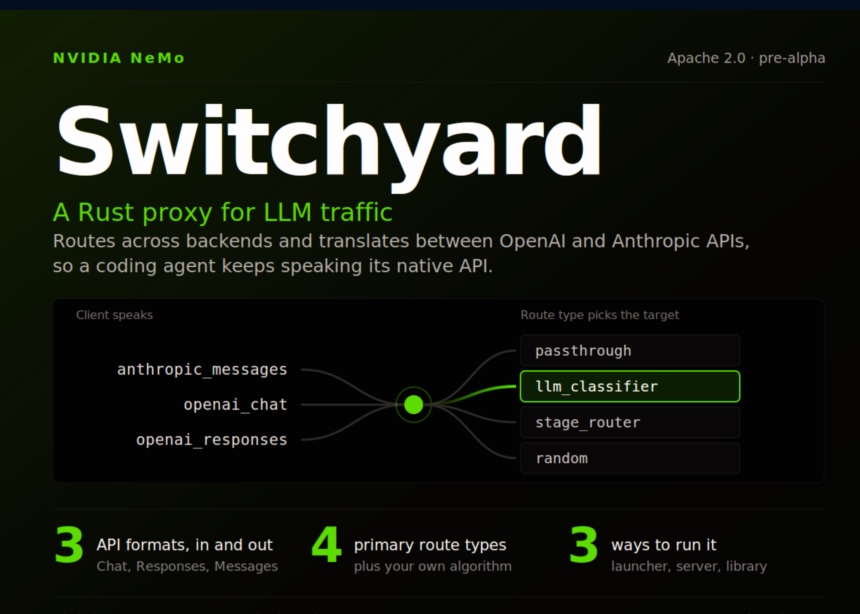
NVIDIA Switchyard emerges as a solution to this fragmentation. It functions as a lightweight, Rust-based proxy and library that acts as a translation layer. By intercepting traffic, it decodes proprietary vendor requests into a provider-neutral internal schema before routing them to the desired backend, re-encoding the requests, and normalizing the responses—including complex streaming event chains—back into the format the client expects.
Architectural Core: The Translation Pipeline
The system operates on a decoupling principle: the agent-facing API and the model-facing API are treated as independent variables. The server component supports three primary wire formats: OpenAI Chat Completions, OpenAI Responses, and Anthropic Messages. Any one of these can be mapped to any backend model.
This decoupling is facilitated through three primary deployment modes:
- Launcher Path: Designed for local development and testing, this allows developers to launch existing CLI tools—such as Claude Code or OpenAI-compatible binaries—directly against proxied infrastructure using a simple command like
switchyard launch. - Server Path: A standalone, production-ready proxy binary that can be deployed as an intermediary layer in a distributed infrastructure, complete with configurable routing and granular observability.
- Library Path: For teams building their own Rust-based custom proxy or application,
switchyard-libsyprovides the core routing logic, leaving the HTTP stack and transport implementation to the developer.
Configurable Routing Strategies
Switchyard handles traffic distribution through a set of explicitly defined routing algorithms. Unlike traditional load balancers, these algorithms are aware of LLM-specific operational context:
| Routing Algorithm | Use Case |
|---|---|
passthrough |
Standard proxying with no target splitting. |
random |
Traffic splitting with optional weighting and seed-based reproducibility for A/B testing. |
llm_classifier |
Uses a “judge” model to evaluate request complexity and route to specific tier-based targets. |
stage_router |
A signal-driven approach that analyzes past tool results and agent progress to route traffic without expensive additional classifier calls. |
Observability and Operational Metrics
Switchyard provides deep visibility into LLM operations by exposing Prometheus-compatible metrics through a GET /metrics endpoint. Crucially, it distinguishes between standard infrastructure metrics and model-specific performance indicators.
Operators can track the switchyard_routing_overhead_ms metric to measure the latency introduced by the routing logic itself. Because classifier-based routes introduce their own latency, these are appropriately categorized. The system also tracks:
- Token Usage: Granular counts for prompt, completion, cache-hit, and reasoning tokens.
- Latency Distributions: P95 and P99 monitoring for model-call latency and full-turn turnarounds.
- Session Statistics: Accessible via
GET /v1/routing/session-stats, offering a summarized view of token usage and call volume partitioned by specific routing sessions.
Security and Configuration Nuances
The configuration utilizes a tiered TOML structure. Security is built into the design, as the proxy is specifically architected to avoid storing secrets in configuration files. Instead, it references environment variables via the api_key_env property. The retry logic is robust by design, with default policies covering common transport failures, 429 rate-limit errors, and 5xx server-side outages.
While powerful, users should exercise caution: NVIDIA currently categorizes Switchyard as pre-alpha and experimental. It is not intended for production-grade workloads, and users should expect breaking API changes as the project evolves toward v1.0. It is best treated as an evaluation and prototyping tool for complex multi-model agent deployments.



