

A Shift in Video Reasoning Architecture
For too long, the default approach to video-based artificial intelligence has been computationally expensive and architecturally blunt. Traditionally, large language models (LLMs) analyzed video by ingesting the entire timeline at a rigid frame rate of one frame per second. Whether the request was a general summary or a highly specific search for a single visual cue, the model was forced to process every second of the clip. This created an unavoidable technical trade-off: engineers had to choose between paying for the full, high-cost context window or breaking the video into arbitrary chunks, which frequently resulted in the loss of critical temporal details.
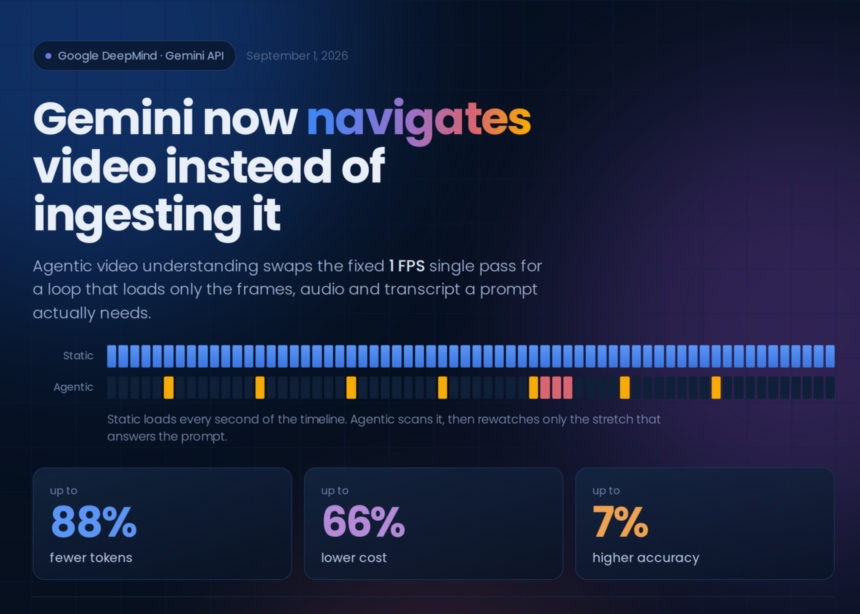
Google has officially pivoted away from this static approach with the launch of Agentic Video Understanding, now available across its latest Gemini Flash models. Instead of blindly ingesting the entire video, the model now functions as an agent that navigates the media, intelligently deciding which segments to inspect, at what resolution, and at what frame rate. This move is significant, not just for the efficiency gains, but for the fundamental change in how models interact with large-scale media assets.
Performance and Efficiency Gains
The technical shift centers on replacing a single-pass processing pipeline with a reasoning loop. When a developer triggers this mode, Gemini performs a series of inspections—searching and scanning frames, audio, and transcripts—and loads only the specific, high-value segments required to satisfy the user’s prompt. The efficiency metrics are stark, particularly for long-form content.
Google reports that this agentic architecture leads to the following performance improvements in comparison to legacy, static processing methods:
- Token Reduction: An impressive decrease of up to 88% in total tokens required.
- Cost Optimization: A reduction in inference costs of up to 66%.
- Accuracy Improvements: Up to 7% higher accuracy scores on industry-standard video reasoning benchmarks.
Technical Implementation and Deployment
This capability is currently provided as a managed, cloud-native feature within the Gemini API ecosystem, specifically through Google AI Studio and the Gemini Enterprise Agent Platform. It is important to note that this is a hosted service; there are no open-weight components or local self-hosting options. The feature supports both uploaded files and direct links to public YouTube URLs. From a billing perspective, it uses standard Gemini API token pricing, with no supplemental feature surcharges.
To implement the feature, developers specify the processing type within their API call:
interaction = client.interactions.create(
    model="gemini-3.7-flash",
    input=[
        {
            "type": "video",
            "uri": "https://youtu.be/7Z5Vy9JBANs",
            "processing": "agentic"
        },
        {
            "type": "text",
            "text": "What are the 3 most important announcements in this keynote?",
        },
    ],
)
Understanding the Internal Loop
Under the hood, the API response now includes two specialized step types: processing_call and processing_result. These steps appear within the steps array, interweaving with the model’s thought processes. This structure allows developers to build real-time progress indicators in their user interfaces, as the model explicitly communicates its requests to inspect specific segments.
The token consumption model is split between these new capabilities:
| Token Type | Source of Consumption |
|---|---|
| Thought Tokens | Navigation reasoning and high-level strategy decisions. |
| Tool-Use Tokens | The actual loading of visual frames, audio, and transcript data. |
Strategic Deployment Guide
While Agentic Video Understanding is the new gold standard for long-form analysis, it is not a universal replacement for static processing. The following deployment logic remains critical for engineers:
- Choose Agentic Mode: For long-form content, multi-hour recordings, or queries that target a specific moment or semantic answer.
- Choose Static Mode: For short clips (under 5 minutes) or use-cases requiring frame-by-frame precision across the entire video, where custom frame rate control and explicit clipping offsets are required.
By delegating the navigation loop to the model itself, Google has effectively removed the development overhead previously required to build custom pre-processing or chunking pipelines, setting a new expectation for video-enabled agentic systems.



