

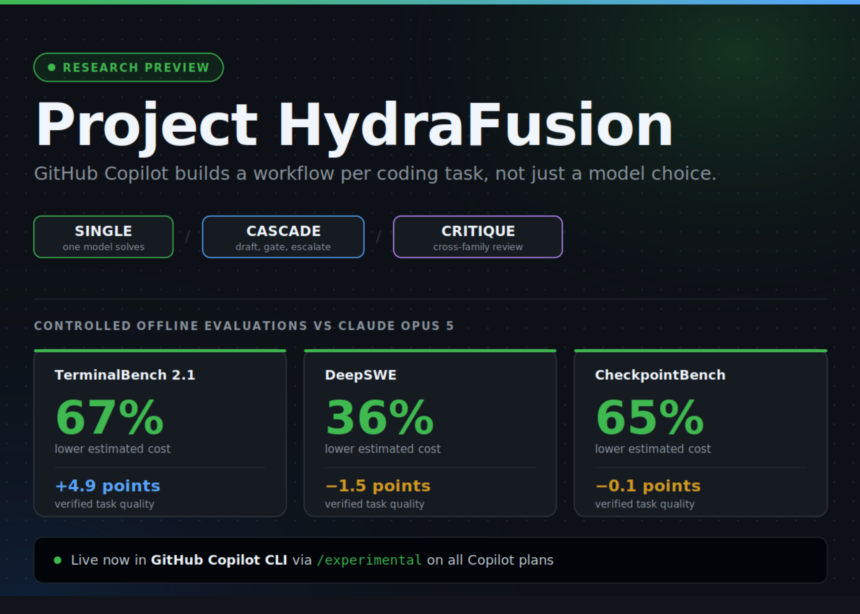
The Shift from Static to Dynamic AI Workflows
In the evolving landscape of software engineering, we are moving beyond the era where simply choosing a single large language model (LLM) for every task sufficed. The industry standard has shifted toward model orchestration, and GitHub is leading this charge with its latest announcement: Project HydraFusion. Rather than relying on a static configuration, this new runtime environment, now in research preview for the GitHub Copilot CLI, actively manages a sophisticated, multi-model execution path tailored for every specific coding task.
The core philosophy here is that model selection should be an optimization problem solved at runtime. By evaluating capability signals—such as the requirements for deep reasoning, code generation, debugging, or complex tool interaction—the system dynamically determines the most efficient workflow to reach a high-quality result while minimizing computational expenditure.
Orchestration Patterns: How HydraFusion Processes Requests
When a developer initiates a request within the Copilot CLI, the system does not immediately fire a generic prompt. Instead, it selects one of three distinct execution patterns:
- Single: The router identifies that a specific, highly capable model can resolve the task independently. This pattern is prioritized to maintain low latency when complex reasoning or review loops are unnecessary.
- Cascade: This pattern uses a tiered approach. An efficient, lower-cost model drafts an initial solution. A built-in quality gate evaluates this draft; if it fails to meet predefined standards, the system automatically escalates the task to a more powerful, specialized model.
- Critique: Designed for high-stakes code generation, this pattern forces the drafting model to present its work to an independent reviewer from a different model family. The review occurs in an isolated, tool-less context, and the original model revises the code based on that feedback.
Engineering Guardrails and Runtime Integrity
Implementing a system that invokes multiple models requires robust infrastructure. GitHub has engineered HydraFusion around several critical operating principles:
- Full Accounting: The system maintains detailed logs of every action, including drafting, critique, revision, escalation, and fallback attempts.
- Bounded Execution: To prevent runaway costs or latency, every leg of the workflow is subject to strict timeouts and explicit cancellation conditions.
- Isolated Reviews: To ensure unbiased evaluation, the critic model operates within a restricted, read-only context, preventing it from having unintended access to the repository filesystem.
- Fail-safe Application: No changes are committed to the codebase unless the workflow completes successfully and passes all internal validations.
Performance and Cost Efficiency
The impact of this runtime orchestration is significant, particularly when benchmarked against industry standard models like Claude Opus 5. The following data highlights the performance gains and cost reduction observed in GitHub’s internal testing:
| Benchmark | Estimated Cost vs Opus 5 | Verified Task Quality vs Opus 5 |
|---|---|---|
| TerminalBench 2.1 | 67% lower | +4.9 points |
| DeepSWE | 36% lower | -1.5 points |
| CheckpointBench | 65% lower | -0.1 points |
The results demonstrate that by intelligently routing tasks—rather than defaulting to the most expensive model for everything—the system can achieve better or comparable quality while dramatically reducing token consumption. The internal CheckpointBench, which leverages real-world sessions and immutable public commits, serves as the primary validation for these reliability metrics.
Getting Started
Project HydraFusion is currently available as a research preview within the GitHub Copilot CLI for all existing plan holders. To enable it, ensure your CLI is updated, run /experimental on, and select HydraFusion (Research Preview) via the /model command. Billing remains transparent, with costs calculated based on the standard per-token rates of the specific models invoked during the workflow execution.



