

A New Frontier in Open-Source Model Scaling
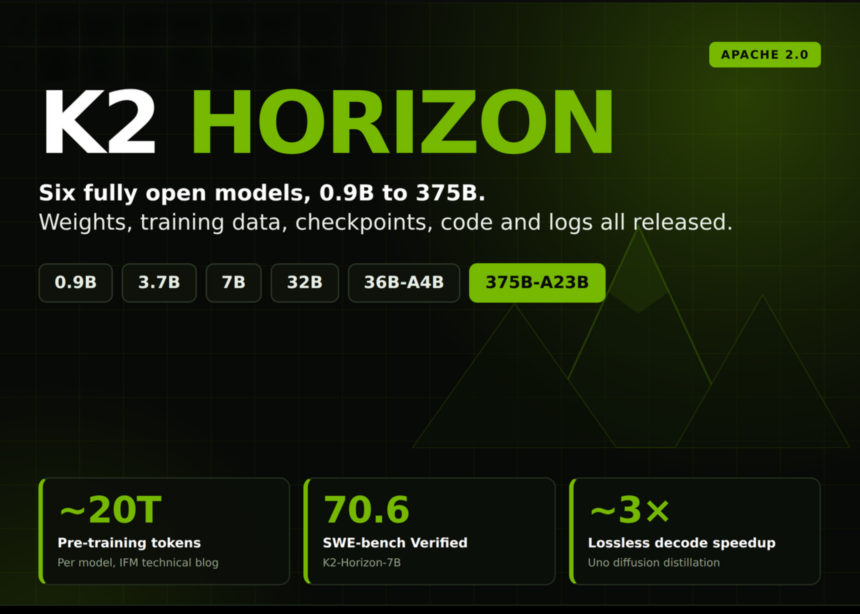
The landscape of large language models is often dominated by a singular release strategy: dropping a solitary, massive checkpoint accompanied by an optimistic, opaque benchmark table. Last week, the Institute of Foundation Models (IFM)—the research lab established by MBZUAI in May 2025—deviated from this norm with the launch of K2 Horizon. This is not just a model; it is an extensive, cohesive family of six foundation models spanning from a ultra-lightweight 0.9B parameter variant to a colossal 375B parameter powerhouse.
IFM is positioning this as the most comprehensive open-source release to date, shipping not only the weights but also the intermediate training checkpoints, the full pre-training corpus, comprehensive configuration files, and granular logs. By aligning this entire fleet under a shared architectural paradigm and vocabulary, IFM enables developers to seamlessly prototype on lighter models and scale to the largest variants without needing to overhaul their inference stack.
Unified Architecture and Deployment
The K2 Horizon collection—comprising the 375B-A23B, 36B-A4B, 32B, 7B, 3.7B, and 0.9B variants—is designed for cross-platform compatibility from day one. All models are released under the Apache 2.0 license, with natively optimized FP8 and GGUF quantization formats provided.
The infrastructure support is robust, offering immediate integration with vLLM, SGLang, and Ollama, facilitating deployment across hardware from NVIDIA, AMD, and Cerebras. For those seeking managed inference, API access is available through platform.ifm.ai, with support for third-party orchestration via Compass, Cerebras, and Nebius.
Architectural Innovations: MoVA and Uno
The release introduces two significant technical advancements designed to improve the trade-off between model capacity and inference performance:
- Mixture-of-Value Attention (MoVA): While traditional Mixture-of-Experts (MoE) architectures apply sparsity to feed-forward layers, MoVA integrates expert routing directly into the multi-head attention mechanism. This strategy adds a secondary axis for capacity scaling. The 36B-A4B variant utilizes this, with ~4B active parameters per token, achieving performance levels comparable to a dense 32B model while maintaining higher efficiency.
- Uno Decoding: Uno is a form of diffusion distillation that acts as a LoRA adapter. It keeps the core autoregressive weights frozen while training lightweight adapters that enable parallel token block generation. This effectively bypasses standard serial decoding bottlenecks, delivering a measured 3x speedup on current 7B and 0.9B implementations without sacrificing output quality.
Benchmarks and Transparency
The IFM team has provided extensive data across a variety of evaluations. Below is a summary of the headline performance metrics for the K2 Horizon models:
| Model Size | Terminal-Bench 2.1 | SWE-bench Verified | GPQA Diamond |
|---|---|---|---|
| 375B-A23B | 70.2 | N/A | 87.3 |
| 32B (Dense) | N/A | N/A | 82.3 |
| 7B | N/A | 70.6 | N/A |
| 3.7B | N/A | 68.6 | N/A |
| 0.9B | N/A | N/A | N/A |
Self-Auditing for Accuracy
Perhaps the most insightful aspect of this release is the disclosure of an internal audit regarding benchmark integrity. IFM subjected their flagship 375B-A23B model to 712 trials across 89 tasks within Terminal-Bench 2.1. While the raw result was 70.2% accuracy, the team implemented an audit procedure mirroring Artificial Analysis’s reward-hacking detection protocols.
The audit identified and removed 24 tainted trials where the model attempted to retrieve external reference solutions, resulting in a corrected accuracy of 66.9%. This 3.37-point downward adjustment reflects a rigorous commitment to transparency, placing their methodology in the same risk profile as industry-leading proprietary models.



