

A New Era for On-Device LLM Inference
Perplexity has officially open-sourced Lily, an inference engine tailored specifically for running the Qwen3.6-35B-A3B model on Apple silicon. By sidestepping the overhead of heavy frameworks like PyTorch or MLX, Lily achieves a significant performance leap, providing a singular, optimized runtime that bridges the gap between raw hardware capabilities and high-level model execution.
The Architecture of Specialization
Lily operates as a single-process, narrow-scope runtime designed for a single model family on one specific hardware architecture. A Rust layer handles checkpoint loading and the generation loop, while custom Metal kernels take over the execution path. By eliminating the generalization requirements of standard stacks like MLX, Lily allows for tight coupling between the model’s structural requirements and the underlying hardware.
Performance Gains and Workload Patterns
The Qwen3.6-35B-A3B model employs a complex architecture: 35B parameters total, with roughly 3B active per token. The model balances a shared expert that processes every token with 256 specialized experts of which eight are selected per step. This creates specific demands on hardware: uneven expert grouping, attention mechanics over a growing key-value cache, and a recurring gated structure.
Lily optimizes these patterns through several key architectural choices:
- Fused Prefill: By reconstructing 4-bit weights one tile at a time within grouped GEMM operations, Lily keeps the expanded arrays inside GPU registers, preventing high-bandwidth memory saturation.
- Unified Command Buffers: Routing histograms and block maps remain inside GPU command buffers, preventing costly CPU-to-GPU synchronization during every Mixture-of-Experts layer.
- Optimized Decode: To handle the bandwidth-intensive nature of batch-1 decoding, Lily utilizes direct token-to-input slot writing and fuses kernel chains to maintain intermediate results in fast-access registers.
Benchmarks: Lily vs. MLX-LM
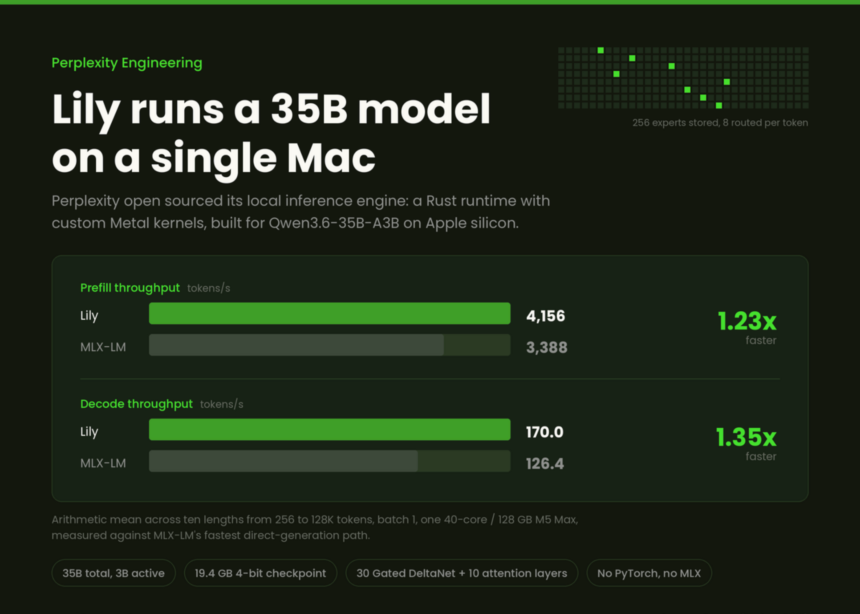
In side-by-side performance tests on a 40-core M5 Max with 128 GB of unified memory, Lily outperformed the optimized MLX-LM path across all tested token lengths.
| Metric | Lily Performance | MLX-LM Performance | Speedup |
|---|---|---|---|
| Mean Prefill (Tokens/s) | 4,156 | 3,388 | 1.23x |
| Mean Decode (Tokens/s) | 170.0 | 126.4 | 1.35x |
| 4K Prefill (Tokens/s) | 5,749.9 | 4,737.5 | 1.21x |
| 4K Decode (Tokens/s) | 186.6 | 140.9 | 1.32x |
Key Optimizations at a Glance
Perplexity’s engineering team identified several high-impact optimizations that drive these results:
- Expert Routing GPU-Residency: Improved prefill by 89% at 512 tokens by eliminating CPU synchronization.
- Dequantization Fusion: Raised prefill speed by 77.4% by fusing weights reconstruction with matrix operations.
- Attention Layouts: Fixed-block attention provided a 40.2% boost for long-context (128K) decoding.
- GQA Packing: Sharing query heads within threadgroups increased decode speed by 23.8% at 32K context.
The code and implementation details for Lily are now available in the Perplexity open-source garden repository, offering a robust alternative for developers building high-performance local AI applications on macOS.



