

Rethinking Machine Learning Efficiency
Modern machine learning research often feels like a race against the limitations of hardware. As autonomous agents become more sophisticated, they can propose, refine, and debug code for machine learning experiments with remarkable speed. However, while the generation of these experimental ideas is computationally inexpensive, the verification process is anything but. Training a single candidate model can tie up specialized GPU infrastructure for anywhere from several hours to days.
This reality presents a critical bottleneck: agents produce far more experimental candidates than a research budget can realistically execute. The strategic decision of which experiments to authorize for training is the primary lever controlling the velocity of research progress. To address this, a collaborative team from FAIR at Meta, University of Oxford, and University College London has moved beyond raw execution toward a formalized framework of research preference, introducing the AI Research Preference Model (RPM).
Architectural Innovation: The Selection Layer
The research team argues that attempting to predict a model’s final performance metric or exact training outcome is often a fool’s errand for an LLM. Instead, their approach centers on relative ranking—deciding which experiments represent the most promising paths forward. This is achieved by integrating the RPM directly into the existing agentic loop, specifically at the child-node creation stage.
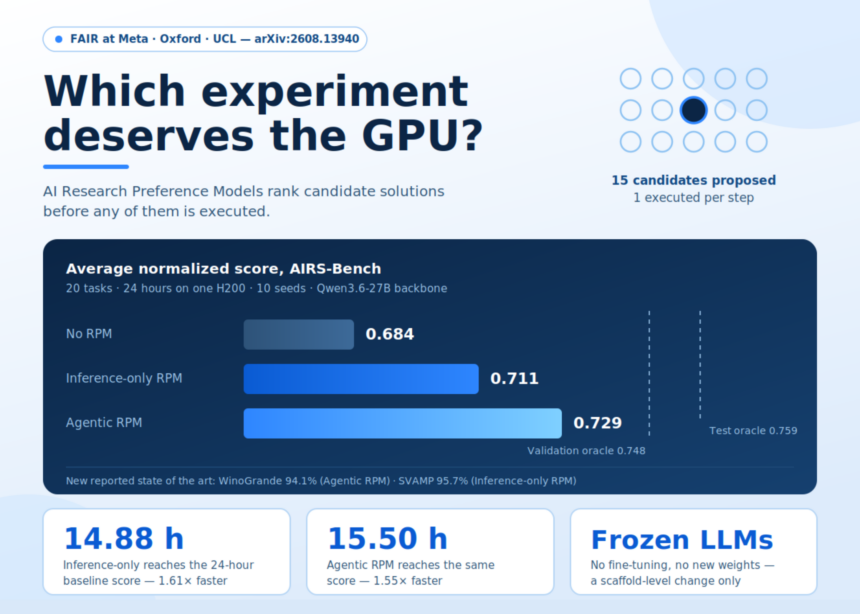
Utilizing the open-source AIRA-dojo scaffold, the agent employs an evolutionary tree search strategy. When it comes time to create a new branch, the agent generates 15 candidate variants in parallel. Rather than choosing one arbitrarily, the RPM conducts a pairwise, knockout-style tournament to identify the superior candidate before a single GPU cycle is spent on training. The decision is grounded by examining context nodes extracted from a Breadth-First Search (BFS) walk of the previously explored tree, complete with their historical validation scores.
Performance Metrics and Benchmarks
The efficacy of the RPM framework was evaluated using the AIRS-Bench suite across 20 distinct text and tabular tasks. The testing methodology constrained every experiment to a 24-hour limit on a single H200 GPU, over 10 random seeds. Remarkably, the backbone models used for both the operators and the judges were the open-weights Qwen3.6-27B, isolating the performance gains directly to the selection logic.
| Selection Methodology | Average Normalized Score |
|---|---|
| Baseline (Random Selection) | 0.684 |
| Inference-only RPM | 0.711 |
| Agentic RPM | 0.729 |
| Validation Oracle (Upper Ceiling) | 0.748 |
| Test Oracle (Upper Ceiling) | 0.759 |
The results demonstrate not only higher ceiling performance but, more importantly, greater capital efficiency. Both the inference-only and agentic versions of the RPM reached the baseline’s final score of 0.684 significantly faster, yielding a 1.5× to 1.6× acceleration in effective research time.
Strategic Deployment Scenarios
The research categorizes the RPM implementation into two distinct architectural tiers:
- Inference-Only RPM: This variant functions as an LLM-as-a-judge, evaluating candidate plans, code blocks, and search history without performing actual trial runs. Its decision logic is enhanced by a prompt optimized via MIPROv2, focusing on extensibility and risk-adjusted potential rather than raw performance forecasting.
- Agentic RPM: This version is more compute-intensive, as it utilizes a sandboxed environment to execute short, lower-fidelity pilot experiments. By analyzing the results of these quick, sub-sampled trials alongside the standard task description, the agentic judge can make highly evidence-based decisions about which full-scale experiment deserves the dedicated 24-hour GPU window.
This work offers a significant step forward in automating the scientific method within machine learning research. By transforming the “which experiment to run” decision from a stochastic guess into an informed, preference-based ranking, the research community can dramatically increase the ROI of their available compute resources.



